Websites are beginning to get something they have lacked since generative AI crawlers arrived at scale: a simpler way to state training preferences without maintaining a growing list of provider-specific rules.
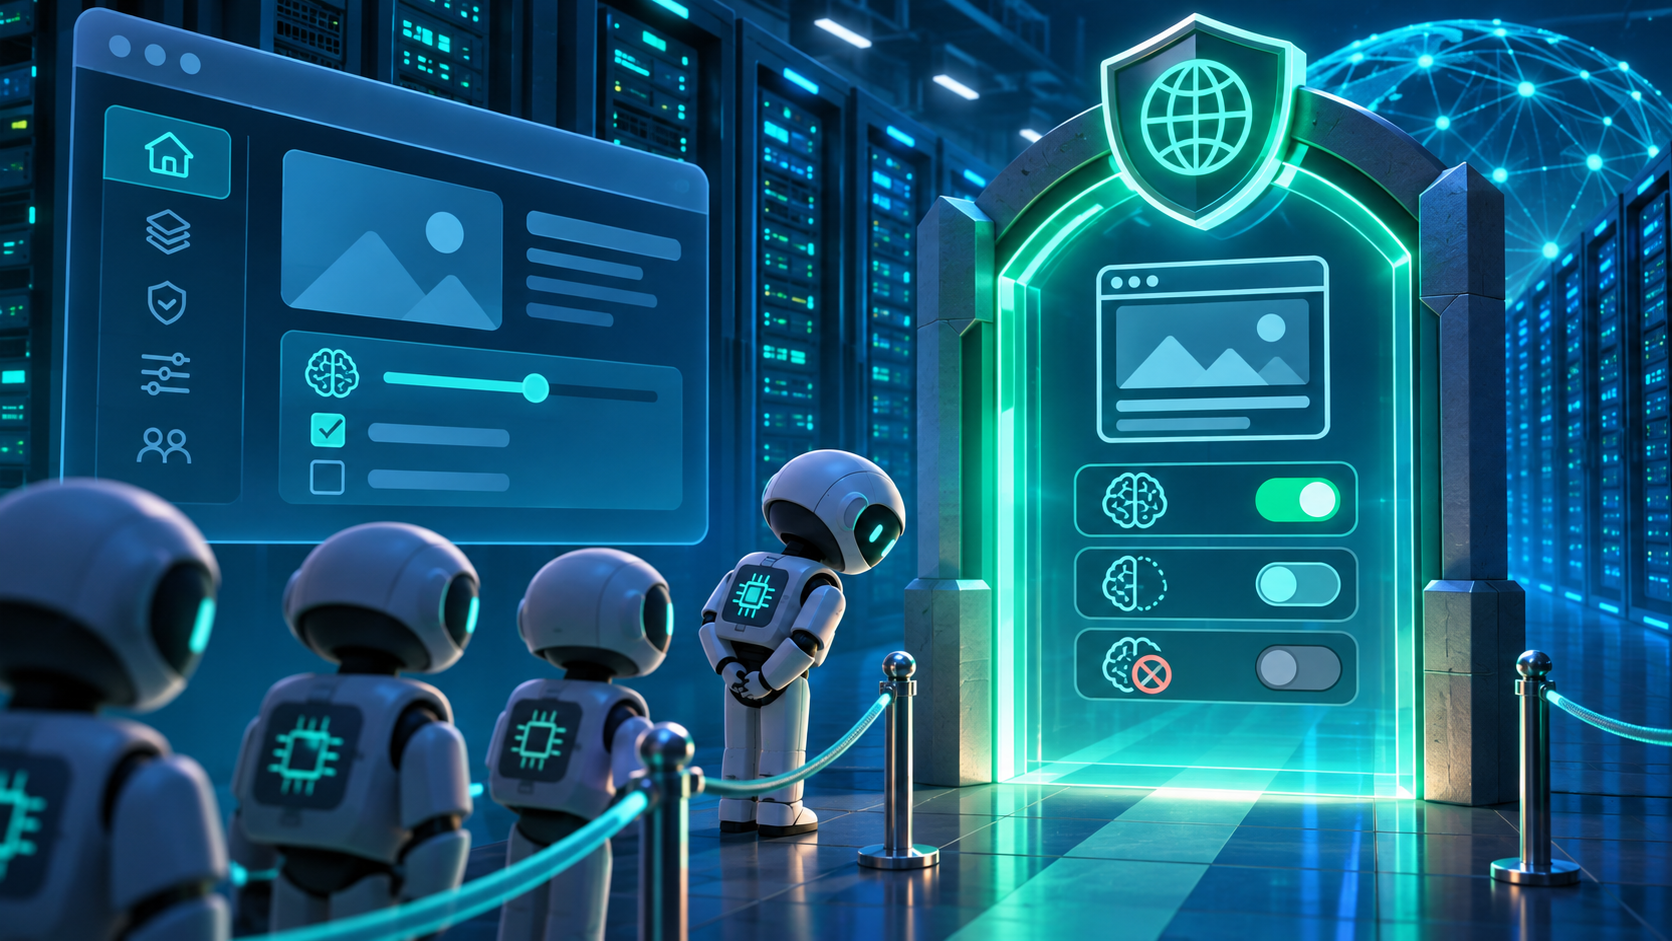
The emerging mechanism is a shared signal carried through robots.txt. Instead of requiring an operator to identify every crawler separately, the signal is intended to communicate one preference to multiple participating AI providers. That sounds like a narrow technical adjustment. In practice, it could become a meaningful layer of web governance.
From crawler lists to a common policy signal
Robots.txt was built around a straightforward convention: site owners publish instructions and automated agents decide whether to follow them. The file is easy to deploy, but the modern crawler landscape has made it harder to manage. Search indexing, retrieval, model training and other automated uses may be handled by different agents, each with its own identifier and documentation.
A common training-preference signal reduces the operational burden. One policy can be expressed once and recognized by many providers. For publishers running multiple domains, the savings are not trivial. Central policy teams can define an organizational position, while engineering teams implement it consistently across properties.
Why this is governance, not just configuration
The important change is not the syntax itself. It is the possibility of a shared expectation between website operators and AI developers. A broadly implemented signal can create a common baseline for communication, auditing and compliance. Operators gain a clearer way to document their intent. Providers gain a standardized input that can be incorporated into crawler and training pipelines.
That does not automatically settle questions about law, licensing or fair use. A voluntary technical signal is not a substitute for contracts, legislation or court decisions. It is better understood as operational infrastructure: a machine-readable statement that can support policy, while leaving the underlying legal questions to the appropriate processes.
Implementation will determine credibility
The credibility of the mechanism will depend on details that are still developing. Providers will need to explain when they read the signal, how quickly changes take effect, which systems honor it and how exceptions are handled. Website operators will need tools to test whether their rules are well formed and deployed across every relevant hostname.
There is also a distinction between future model training and other uses of web content. Search, user-triggered retrieval, security scanning and archival functions are not identical activities. A durable standard will need enough precision to avoid turning one preference into a catch-all instruction whose meaning varies from provider to provider.
A new responsibility for web teams
For companies, robots.txt is moving closer to a policy surface. Decisions that were once left to search specialists may now require input from legal, editorial, data and product teams. The right setting depends on the organization’s business model: an open documentation project, a subscription publisher and a software company may have very different priorities.
See also: AI platform
Governance should therefore start before deployment. Teams need an inventory of their public domains, a named owner for crawler policy, a review process for changes and a record of the rationale behind each instruction. They should also avoid assuming that a signal is universally honored until providers publish their implementation details.
The larger opportunity
A common preference signal is modest compared with the broader debate over AI and the open web. Yet standards often begin with modest, interoperable building blocks. If adoption expands, the signal could reduce friction for site operators and make provider behavior easier to evaluate.
The strategic lesson is that web governance is becoming multi-party infrastructure. Content owners need controls that are understandable and scalable. AI providers need consistent inputs. Standards bodies need room to refine definitions as technology evolves. A shared signal cannot solve every dispute, but it can make intentions clearer—and clarity is a useful foundation for whatever rules come next.